
Together Post-Training
You shape the model. We bring out its best.
Quality across training and generation. Engines tuned for every model. You train better models, iterate faster, and lower compute costs.
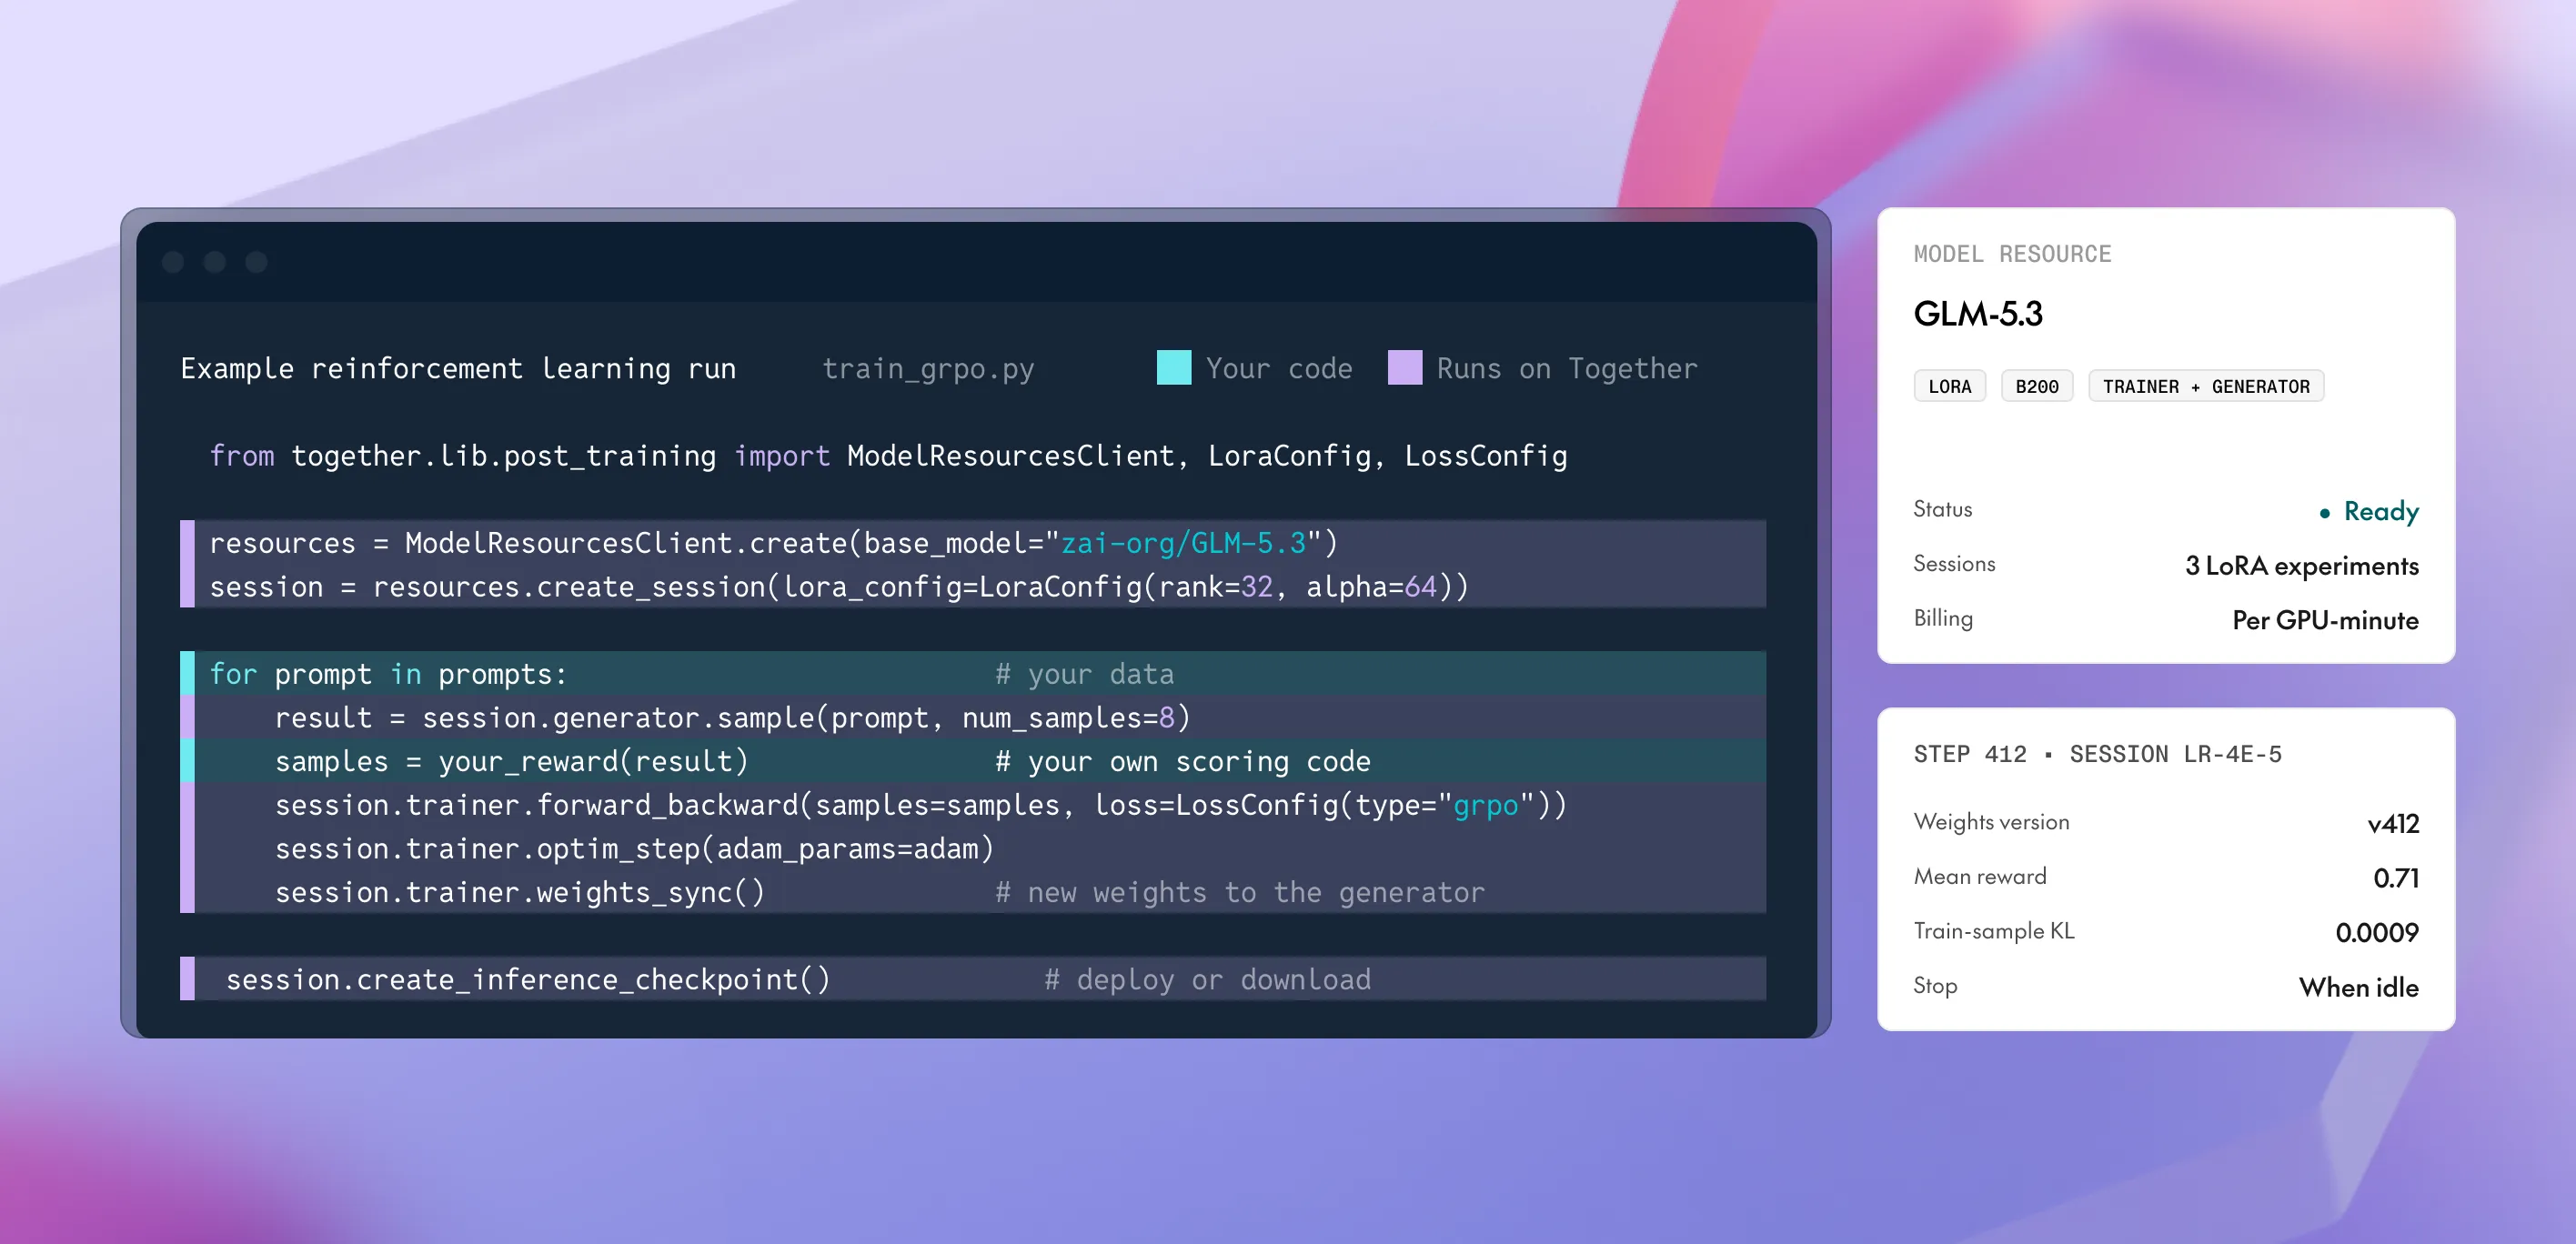
Own the training loop. We’ll do the hard infra.
Write the recipe with your data and rewards. Together optimizes how it trains, and after that, the model’s all yours.
- You control
Your recipe via a simple API.
Data, prompts, and environmentsRewards, verifiers, and judgesGRPO, PPO, or custom lossesMulti-LoRA or full-weightWhere the trained model is deployed - Together handles
The engineering under every run.
On-demand or dedicated GPU capacityTraining–rollout consistency for RLOptimal parallelism setupRollout engines tuned for each modelAsync or sync training support
Built for fast, quality iteration
Write your loop in Python, run parallel experiments, and deploy the winner.

Write your loop in Python
 RL or SFTCookbook recipesTinker-compatible
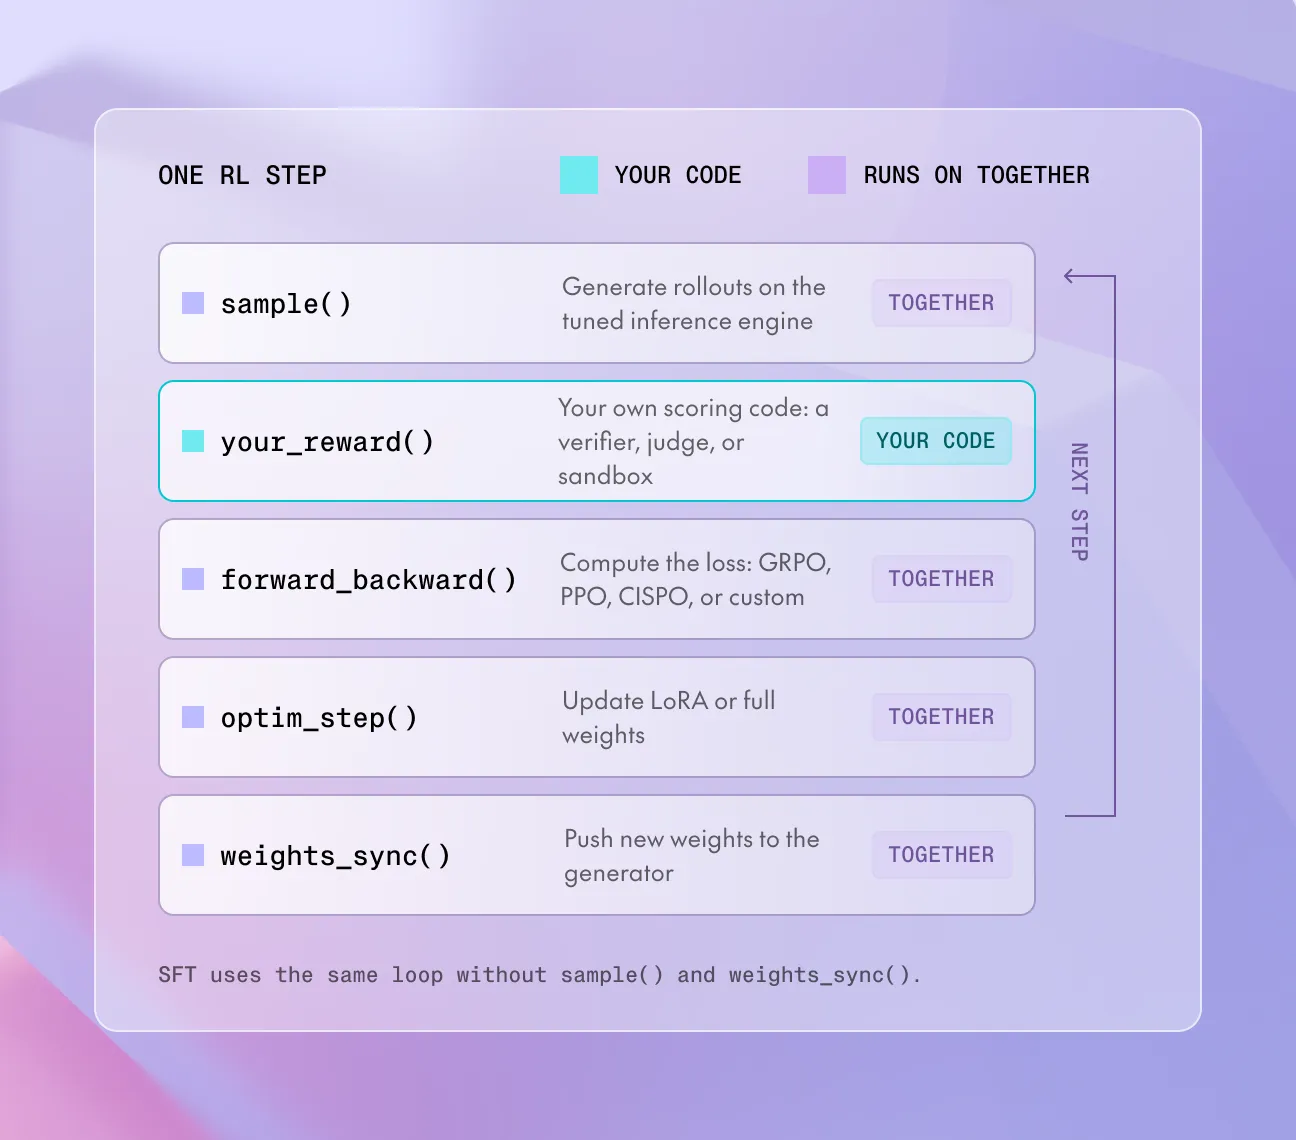
One RL step is sample(), your_reward(), forward_backward(), optim_step(), and weights_sync(). SFT uses the same loop without sample() and weights_sync().

Run parallel experiments
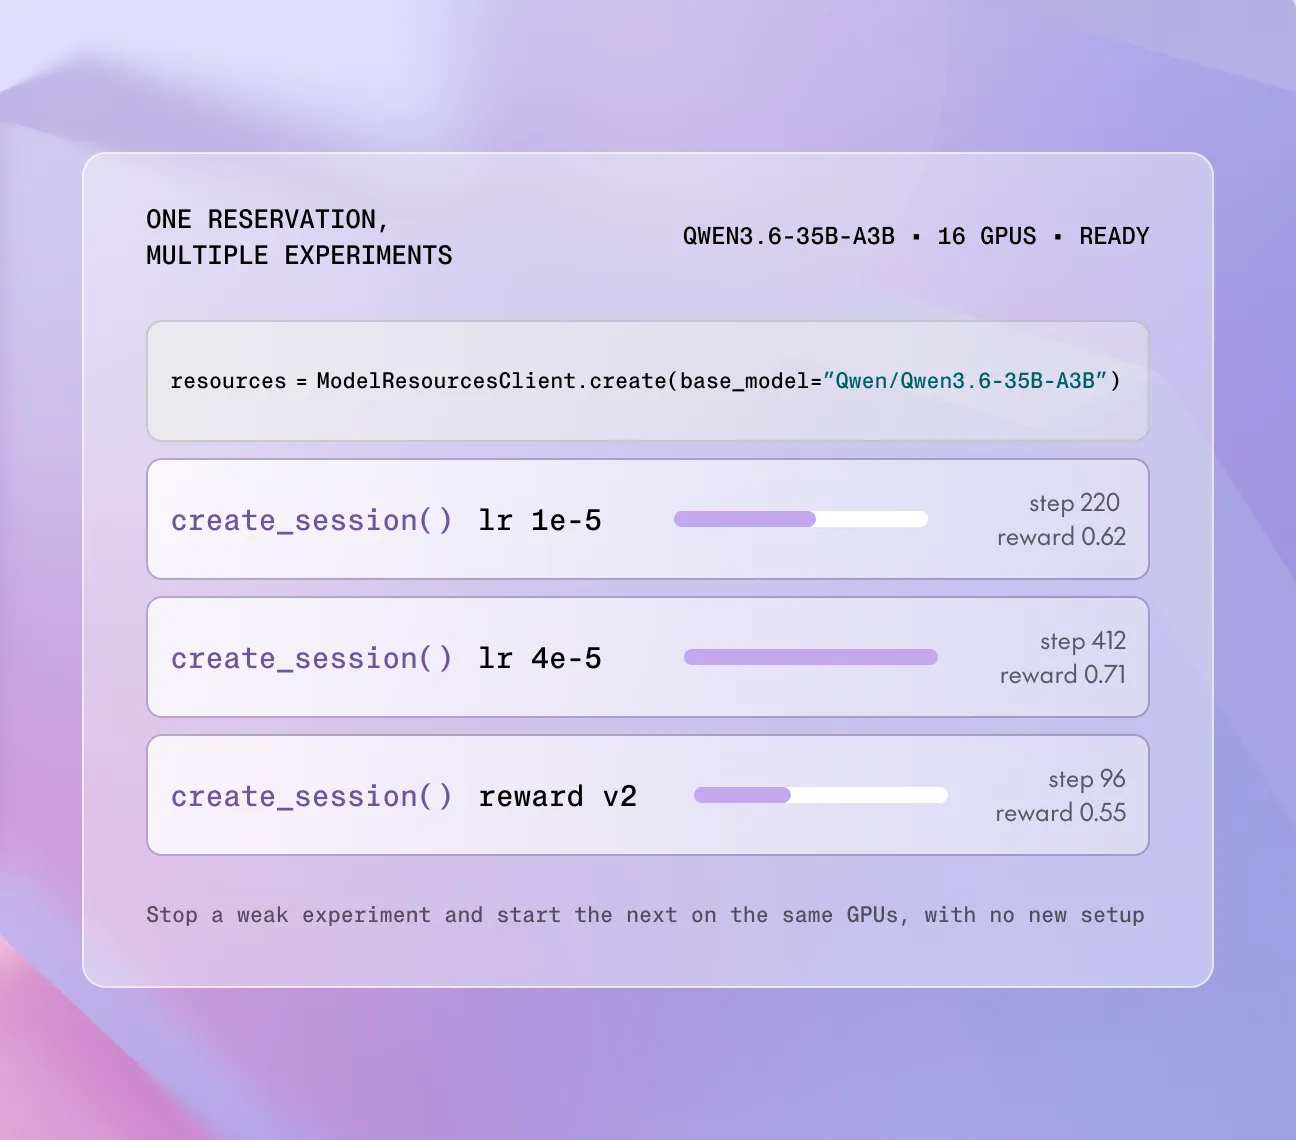
One-call setupParallel LoRA sessionsYour own trackingOne call reserves every GPU the model needs, with a setup already tested for it. Open a session for each experiment on the same reservation, and track results in your own tools, like Weights & Biases.

Compare and deploy
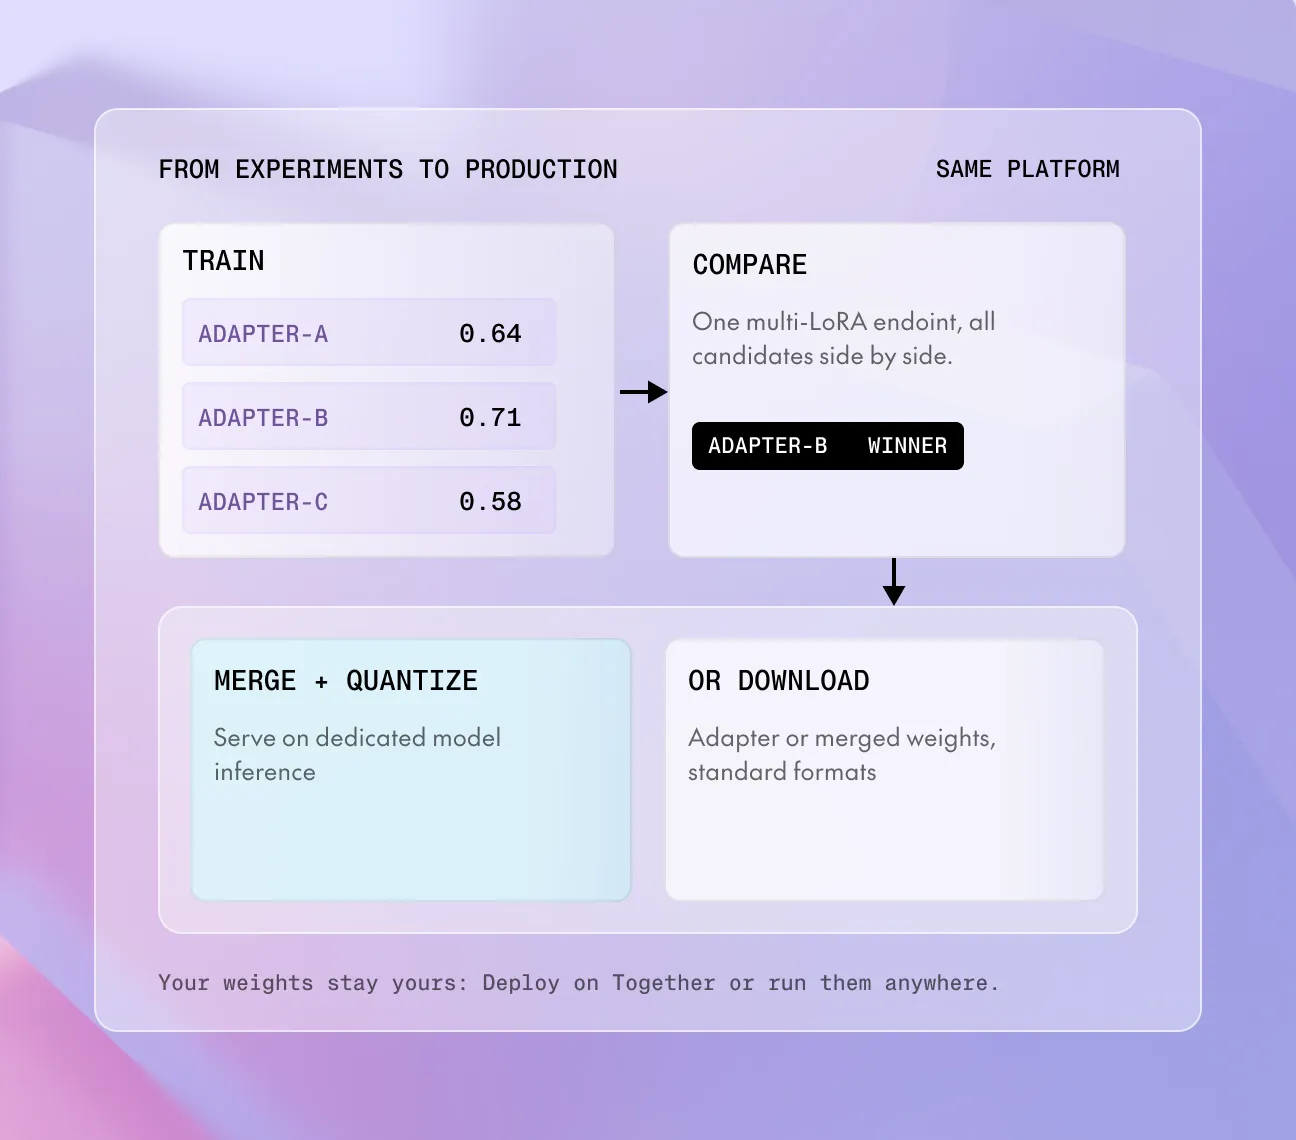
Multi-LoRA evalDedicated endpointStandard formatsSave a checkpoint, compare adapters side by side on one multi-LoRA endpoint, then deploy the winner on Together or download the weights to run anywhere.
Quality, performance, and efficiency, built into every run
The hard parts of post-training, handled under your loop, and what each one gets you.
Generator and trainer, kept in sync
GLM-5.3
Tokendefsolve(n):returnnGenerator logprob-0.118-1.842-0.031-0.412-0.079-0.951-0.274Trainer logprob-0.119-1.845-0.031-0.410-0.080-0.954-0.273Experts used12·8740·1317·8712·663·14040·9912·66Experts replayed12·8740·1317·8712·663·14040·9912·66Generator (writes the rollout)Trainer (learns from it)Quality that holds up
The trainer matches the generator’s output precision, replays its expert choices on supported mixture-of-experts models, and corrects for samples from older model versions in every RL loss. Safeguards stop a bad step instead of training on it, for RL and SFT alike.
learn moreMore RL steps in the same amount of time
Untuned stack1+ stepsOn Together4+ stepsGenerateYour rewardTrainSyncEngines tuned for every model
Rollout engines use precompiled GPU execution for faster generation. Prefix caching, packed training, and GPU-to-GPU weight sync shorten the rest of each step, and async lets generation and training overlap.
learn morePer-GPU pricing
Cost per rolloutToken-based pricingEach rollout costs lessBreak-evenPer-GPU pricingRollouts at once →More training per dollar
Prefix caching reuses what the model has already read, so multi-turn rollouts process fewer new tokens. Across every run, GPUs bill per minute only while ready, several LoRA experiments share one reservation, and SFT skips generators, so more of every GPU-hour goes into training.
learn more
Post-train frontier open models
Each model ships with a tested configuration for training and generation.
 Z.aiGLM-5.3
 Moonshot AIKimi K3
 QwenQwen3.8 27B
- QwenQwen3.6 35B A3B
- More frontier modelsComing soon
From trained model to production, on one platform
Serve where your model already lives, so nothing gets lost in a handoff. Or take the weights with you.

Multi-LoRA training
Train several LoRA experiments at once on one reservation, each in its own session, at no extra hourly cost.
Best for

Multi-LoRA evaluations
Load every trained adapter onto one multi-LoRA endpoint and compare them side by side on the same traffic.
Best for

Serve in production
Merge the winning adapter into the base model, quantize it, and serve it on dedicated model inference.
Best for
Post-training FAQ
Can't find the answer you need? Talk to an expert.
What do I write, and what does Together handle?
You write the recipe: data, rewards, environments, the loss, and the training loop, in Python. Together runs the trainer and, for RL, the rollout engine and weight sync between them, with each model's setup already tuned.
Do you provide reward models or sandboxes?
Rewards and environments are your own code, and they work with any sandbox. Your script calls Together to generate each response, runs any actions in your sandbox, scores the result with your verifier or judge, then sends the training signal back.
Can I train multi-turn agents?
Yes, with RL. Your script runs each episode: Together generates each turn, and your code runs tool calls in your own sandbox and sends the results back. Earlier turns stay cached on the GPUs that hold them, so each new turn processes only what’s new.
How is post-training priced?
By the GPU-minute, only while your model resource is ready. Queueing, startup, and shutdown are free, and resources stop after an hour without activity. You can check the hourly price of a configuration before you create it.
Should I train with LoRA or full weights?
Low-rank adapters (LoRA) need fewer GPUs and let several experiments share one reservation. Full-weight training updates every parameter when an adapter isn't enough. Availability depends on the model.
Should I use sync or async RL?
Sync keeps every sample on the latest weights. Async overlaps generation and training for faster steps, with samples one step behind, and the loss corrects for the gap. Start with sync, then switch to async when step time matters.
How do I deploy a trained model?
Save an inference checkpoint, compare adapters on a multi-LoRA endpoint, then serve the winner on dedicated model inference. Or download the weights and run them anywhere.