Introducing Polymorphic Inference, starting with Together Compiler →

Introducing Together Post-Training: Better models, faster runs, lower costs →

Introducing Together Link: Run open models inside the harness you already use →

The Open Source AI Stack: models, inference, routers, harnesses & tools →

GLM-5.3 vs. GLM 5.3 Flash on DeepSWE →

⚡ On-demand B200s now available on Together GPU Clusters →

  • Inference

    • Serverless Inference

      High-performance inference as APIs

    • Batch Inference

      Inference for batch workloads

    • Provisioned Throughput

      Token-based capacity with SLAs

    • Dedicated Model Inference

      Inference on custom hardware

    • Dedicated Container Inference

      Inference for custom models

    • Together Link

      Run open models in your harness

    New

    Polymorphic Inference

    Inference that gets better over time

    Explore Top Open-Source Models

    • Chat

    • Image

    • Code

    • Vision

    • Video

    Show all
  • Compute

    Accelerated Compute

    • GPU Clusters

      Reliable GPU clusters at scale

    • AI Factory

      Custom infrastructure at frontier scale

    Developer Environments

    • Sandbox

      Build development environments for AI

    Storage

    • Managed Storage

      Store model weights & data securely

    • GB300

    • GB200

    • B300

    • B200

    • H200

    • H100

  • Model Shaping

    • Post-Training

      Define your own RL and SFT loop

    • Fine-Tuning

      Launch managed SFT and DPO jobs

    • Evaluations

      Measure model quality

    kimi K2.7 Code
    Gemma 4 31B-it FP8
    GLM 5.1 FP4
    OpenAI logo with a symmetrical abstract geometric knot design.
    gpt-oss-120b
    Qwen3.5 397B A17b
    Llama 4 Maverick

    Model library

    Fine-tune top open-source models

  • Research

    • Research

      Systems research for production AI

    • Research blog

      All our research publications

    Featured publications

    • FlashAttention

    • ATLAS

    • Kernel Collection

    • ThunderKittens

    • DSGym

    Show all
  • Developers

    • Documentation

      Technical docs for Together AI

    • Blog

      Our latest news & blog posts

    • Demos

      Our open-source demo apps

    • Cookbooks

      Practical implementation guides

    • Open-source AI

      Build better with open models

    • Together Link

      Run open models in your harness

    • Events

      Explore our events calendar

    • Model Library

    • Playground

    • Together Chat

    • Which LLM to use

    • Open-source ROI calculator

  • Customers

  • Pricing

    • Serverless Inference

      High-performance inference as APIs

    • Batch Inference

      Inference for batch workloads

    • Provisioned Throughput

      Token-based capacity with SLAs

    • Dedicated Model Inference

      Inference on custom hardware

    • Dedicated Container Inference

      Inference for custom models

    • Together Link

      Run open models in your harness

    New

    Polymorphic Inference

    Inference that gets better over time

    Explore Top Open-Source Models

    • Chat

    • Image

    • Code

    • Vision

    • Video

    Show all
  • Accelerated Compute

    • GPU Clusters

      Reliable GPU clusters at scale

    • AI Factory

      Custom infrastructure at frontier scale

    Developer Environments

    • Sandbox

      Build development environments for AI

    Storage

    • Managed Storage

      Store model weights & data securely

    • GB300

    • GB200

    • B300

    • B200

    • H200

    • H100

    • Post-Training

      Define your own RL and SFT loop

    • Fine-Tuning

      Launch managed SFT and DPO jobs

    • Evaluations

      Measure model quality

    kimi K2.7 Code
    Gemma 4 31B-it FP8
    GLM 5.1 FP4
    OpenAI logo with a symmetrical abstract geometric knot design.
    gpt-oss-120b
    Qwen3.5 397B A17b
    Llama 4 Maverick

    Model library

    Fine-tune top open-source models

    • Research

      Systems research for production AI

    • Research blog

      All our research publications

    Featured publications

    • FlashAttention

    • ATLAS

    • Kernel Collection

    • ThunderKittens

    • DSGym

    Show all
    • Documentation

      Technical docs for Together AI

    • Blog

      Our latest news & blog posts

    • Demos

      Our open-source demo apps

    • Cookbooks

      Practical implementation guides

    • Open-source AI

      Build better with open models

    • Together Link

      Run open models in your harness

    • Events

      Explore our events calendar

    • Model Library

    • Playground

    • Together Chat

    • Which LLM to use

    • Open-source ROI calculator

Contact sales
Contact sales
Sign in
Explore Research

Research blog

All
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.
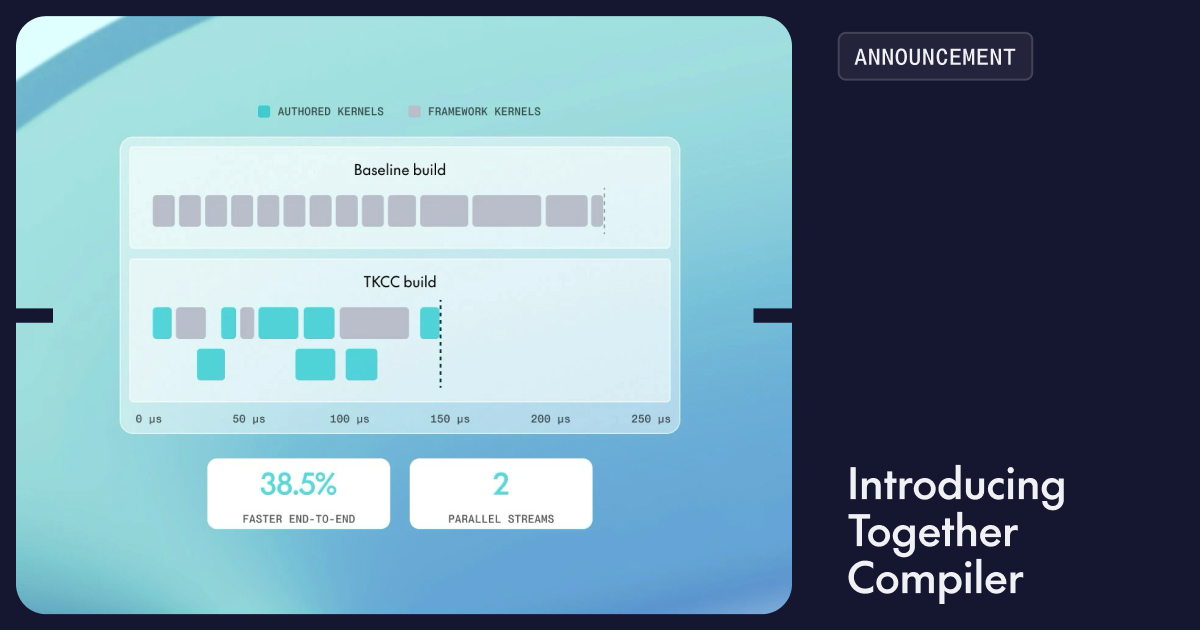
Together Compiler: Continual Compilation for AI inference

Reyna Abhyankar, Dylan Lim, and Simran Arora

Kernels
To Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72!

Dylan Lim, Xinyi Li, Sonny Li, Peter Wu, Dan Fu, Simran Arora

Agents
ThunderAgent: 2x Faster Agentic Inference for Synthetic Data Generation at Scale

A program-level scheduler that eliminates KV cache thrashing, delivering more than 2x single-node throughput and near-linear multi-node scaling for large-scale agentic inference.

Hao Kang, Ziyang Li, Weili Xu, Xinyu Yang, Yinfang Chen, Junxiong Wang, Beidi Chen, Tushar Krishna, Chenfeng Xu, Simran Arora.

Kernels
Together AI at ICML 2026: frontier research across the full stack

Nine papers from Together AI and our peers were accepted to ICML 2026 in Seoul. If you are attending come by booth B714. We’d love to connect.

Together Research

Load more
1 / 21

No search result

Try expanding your search or changing the filters.

Be at the forefront of AI innovation

From optimized training and model shaping to large-scale production inference

See open roles
  • Products

    • Serverless Inference

    • Batch Inference

    • Provisioned Throughput

    • Dedicated Model Inference

    • Dedicated Container Inference

    • Together Link

    • Fine-Tuning

    • Post-Training

    • Evaluations

    • GPU Clusters

    • Sandbox

  • Models

    See all models

    ZAI

    Moonshot AI

    MiniMax AI

    DeepSeek

    Qwen

    Meta

    Google

    OpenAI

    Mistral AI

    Custom models

  • Developers

    • Research

    • Docs

    • Open-source AI

    • OSS ROI calculator

    • Voice Agents

    Pricing

    • Pricing overview

    • Inference

    • Fine-Tuning

    • GPU Clusters

  • Resources

    • Blog

    • Customer Stories

    • Startup Accelerator

    • Support

    Company

    • About us

    • Careers

    • Events

    • Press

  • Privacy Policy

  • Terms of service

  • Cookie Policy

  • Consent Preferences

© 2026 Together AI. All Rights Reserved.