
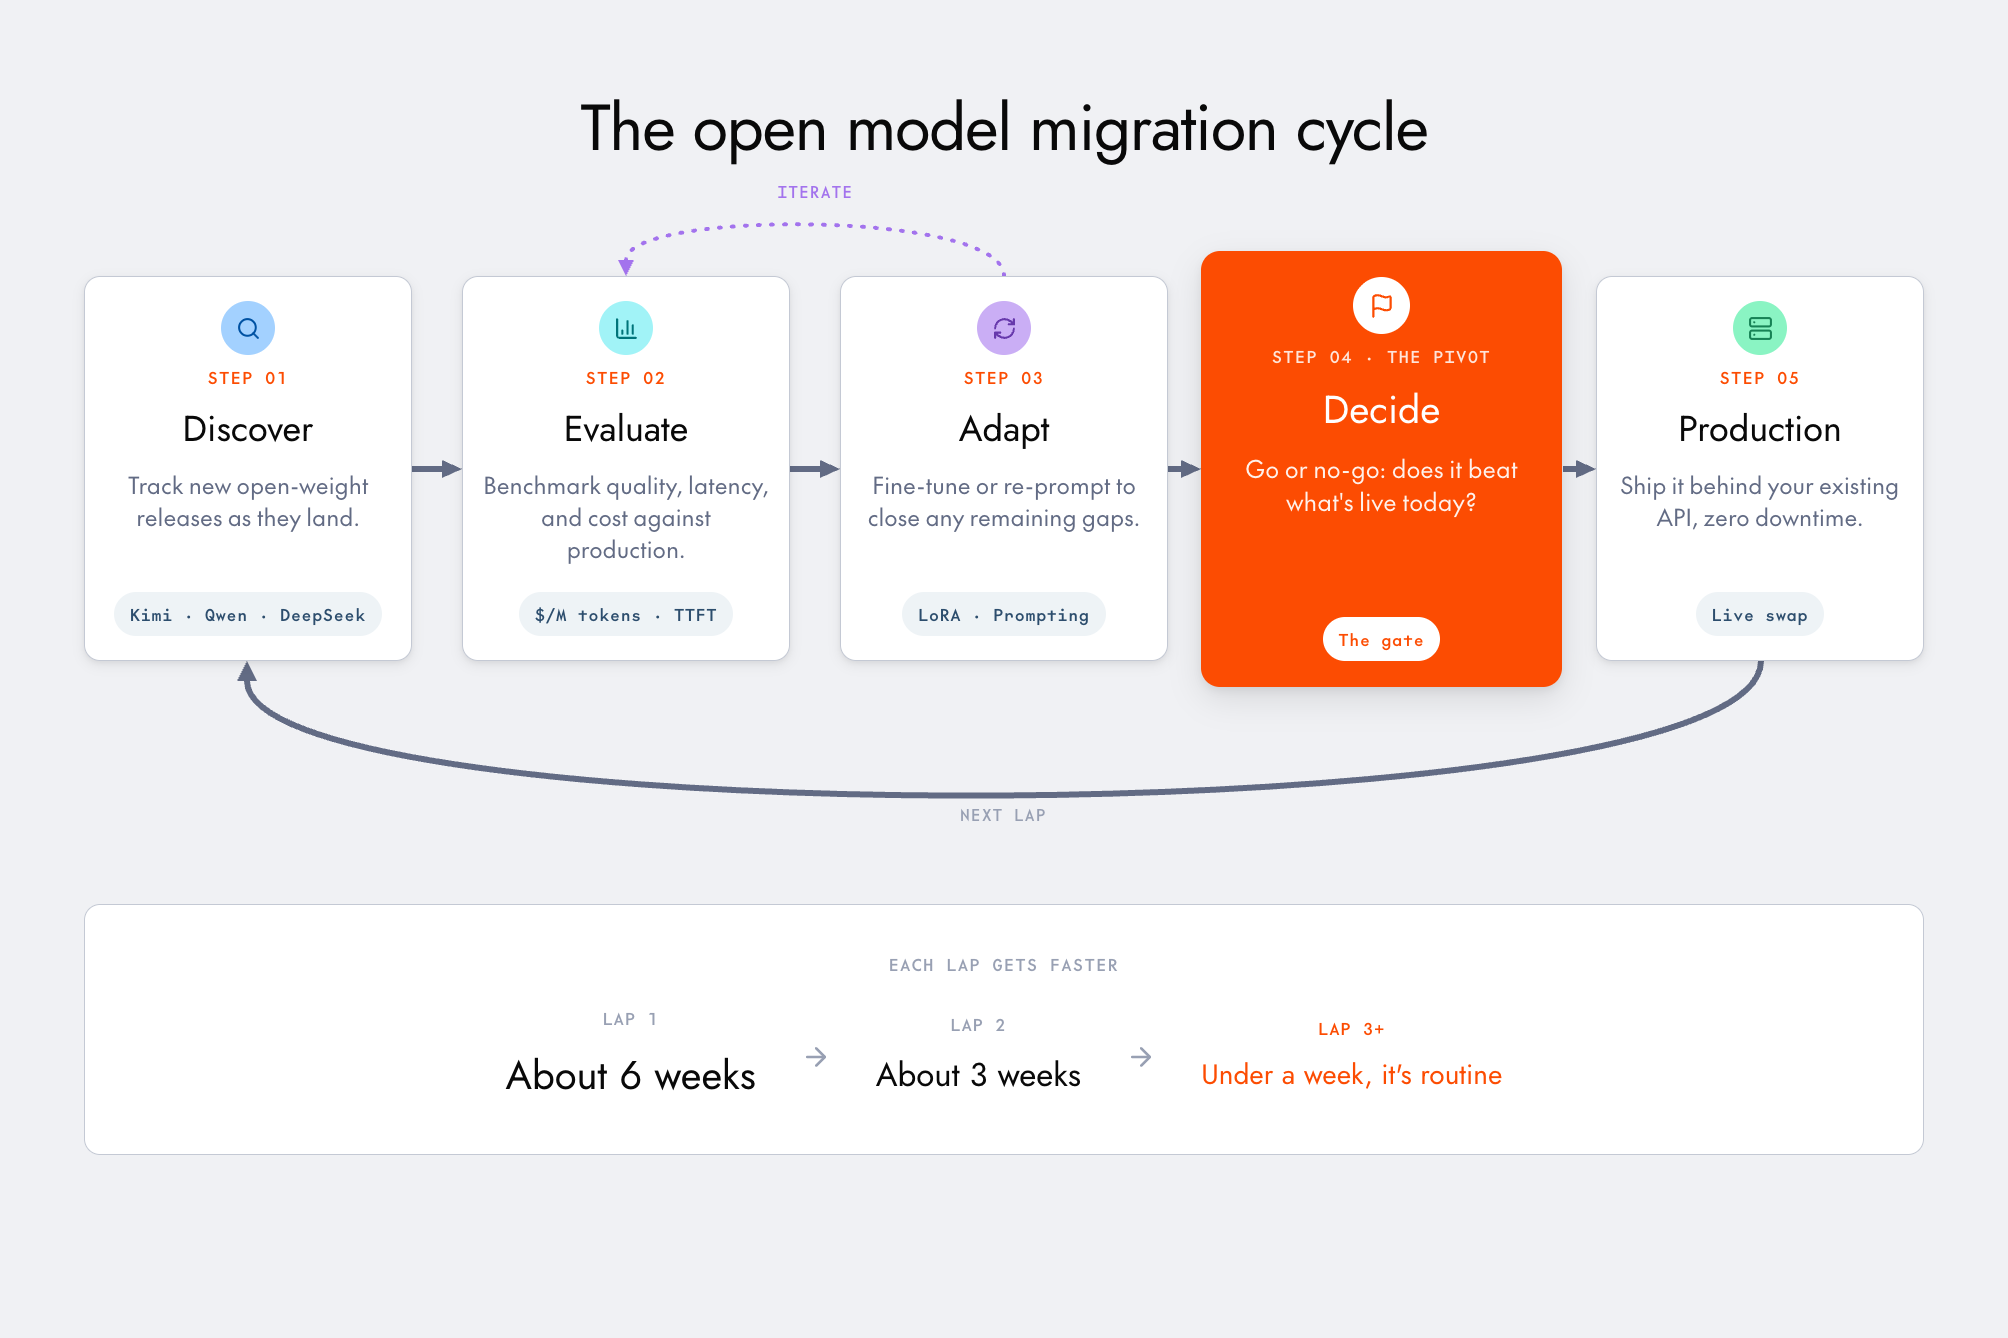
Migrations are the bane of any mature company. Systems are deeply integrated, you have key stakeholders across domains, and a small improvement can take months or years to integrate in traditional cases. Recently, the latest candidate for migration has been closed source to open source models (OSM). The promise of cost savings and distributed ownership of technology has always been compelling. Is it worth it though?
Luckily, closed to open source breaks the tradition of slow and painful migration, especially if you adopt a managed service. These services keep up with the pace of AI innovation while offloading much of the complexity from your business.
Now the blast radius is much smaller, and the technical stack you need to migrate is less complex. Harnesses, gateways, and tooling are all built to adopt a variety of models. You can take full advantage of this for a quick and holistic migration from closed to open source.
We'll walk you through a successful migration strategy we've seen with our customers. This can take weeks to months rather than months to years. In future, we'll also provide assets to help you track your progress along the way.
This is an overview. We will provide deep dives for each section we feel could use more color, with workbooks, examples, and walkthroughs.
Discover
As you start to discover candidate models, the most important thing is to know what you're evaluating for. No single model is the best across the board. Different models have different strengths across domains, and the better you define the problems you want solved, the easier it becomes to shortlist models that will actually work for you. Start by defining your use-case and workload in plain terms: what tasks the model handles, what a good response looks like, and what your traffic actually consists of.
With your use-case defined, pre-existing benchmarks become useful as a filtering tool. Identify the benchmarks most relevant to your work so that leaderboard numbers correlate with performance on your tasks. Good sources of benchmarks include The Open Frontier, Artificial Analysis, Epoch AI, Vals AI, Scale's leaderboards, Intelligence and Arena. Within these you might find the following benchmarks useful:
- Coding agents: FrontierCode, DeepSWE, Terminal Bench 4
- Chat and general assistant work: LMArena, AA-Intelligence Index
- Agents and tool-use: τ-bench, Agent Arena
- Vision: Vision Arena
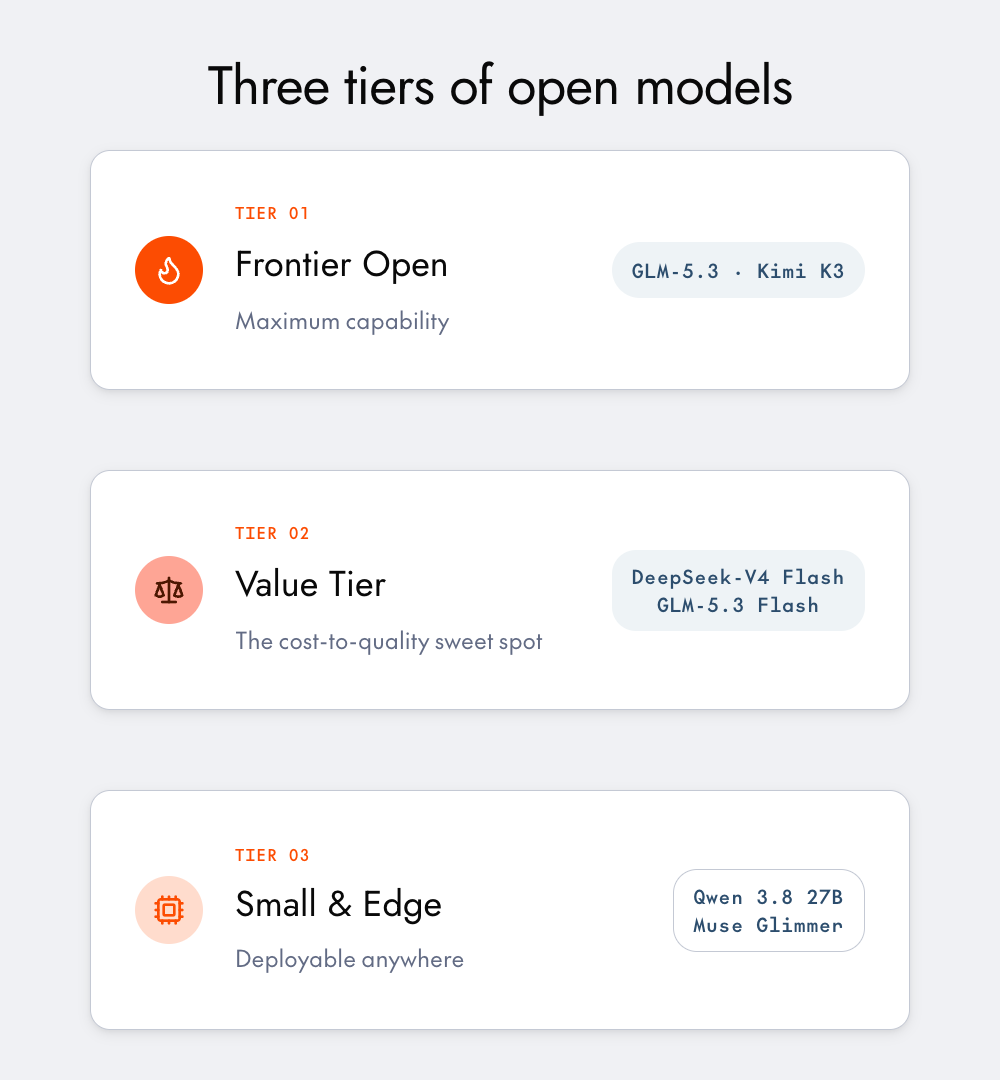
Remember, your job is to identify which of these are relevant for you to narrow down candidate models, we'll talk more about custom evals later. Typically you'll find that there are three tiers of models available to pick from, as shown above.
For your top candidates, go beyond raw performance. Look at cost per task, how many tokens a model burns per attempt, how many steps it needs, end-to-end runtime, and how quickly you can verify a correct answer. Lots of new benchmarks are now reporting these per-task numbers, and we believe these better correlate with actual model cost and performance. A model that scores a few points lower but completes tasks in half the tokens and half the time may be the better fit.
Finally, kick the tires. Take a handful of representative tasks into a playground and see if your shortlisted models perform as expected. Watch for failure modes and ask whether it's the model failing or the harness and context around it. It's also worth seeing what other companies running these models are saying about their experience. You should leave this step with two to three models that you are ready to put through serious evals.
Evaluate
Evaluating models will be the most involved part of this process and certainly needs a blog of its own, but at a high level you will be evaluating two things: accuracy and performance.
Accuracy defines the capabilities of the model. This can include instruction following, summarization, function calling, vision performance etc. This is everything the model can do regardless of where it runs or how fast it is. You want to evaluate if it can solve your workload needs.
Performance covers how well the model runs. This changes based on things like model size and architecture. For these tests we don't care how well the model is responding to requests. We're evaluating whether this model meets the cost and user-feel, or latency, expectations needed to adopt an OSM.
For both accuracy and performance you'll need to have a consistent mindset: benchmarks are directionally useful, true tests are done with real data. The best way to evaluate a workload is not to look up or run generic benchmarks. Workloads have different traffic shapes, niche response requirements, and request structures. No benchmark can represent that except your own. Luckily, if you're already using closed source models, a simple replay of existing traffic is all the data you need to benchmark. No custom suites, no large data set. This is, and always has been, the best way to bench even before we were benchmarking modern frontier models (HPC, databases, load balancing, etc). Ensure you're still testing against the targets defined earlier though.
If you don't have data to replay you're not blocked! We can still size according to general usage patterns like input and output size and expected cache hit rate. If closed source providers don't provide these metrics, gateways like LiteLLM can help gather this information. We'll discuss this technique further in a deep dive blog.
After you've found your data: determine what your goals are. Do you want to save on cost? Speed? Improved or similar quality? When you rerun your data against the new models you've chosen, this is your goal line. You're aiming to meet or surpass this. When OSMs pass this goal line you have technical validation and you can move on to a full scale migration.
Investing in robust evaluation techniques will enable your team to rapidly adopt new OSMs with ease moving forward. In a follow-up blog we'll do a much deeper dive on how to size your workload, rerun traffic, and evaluate results. For now, this is the foundational concept for how to evaluate an OSM.
Adapt
Frontier open models are getting good enough that they typically work out of the box for most applications, but if a model doesn't pass your evals you'll need to adapt. That doesn't necessarily mean the model is a dead end. It usually means the way you're using it was tuned for a different model: the prompt, the sampling parameters, the harness around it. Your closed-source setup carries a lot of accumulated tuning that the open source model has never seen, and most likely you'll need to adapt it.
You have a few levers here, roughly in order of effort:
- System prompt engineering: try asking the model differently. Models are trained differently and might need different prompting to work at the same level as your current closed model.
- Model inference settings: sampling parameters like temperature and top_k, preserved thinking, and reasoning effort can all meaningfully change behavior.
- Context engineering and the harness itself: the skills, tools, and MCP servers that make up the software environment the model operates in.
- Model weights through fine-tuning or distillation: the hardest to pull off, since it requires well-defined evals, curated data, and real experimentation, but it can unlock a niche domain and make a small model punch well above its weight.
Whichever levers you pull, treat this process as an iterative loop. Set up experiments that isolate a single modification, evaluate its impact, and iterate until you find the things that actually improve evals. Keep your evals modular and your experiments simple. If you're testing too many things and changing too many variables at once, you'll never isolate what's working amongst the confounding noise. A suite of well-defined evals, discussed above, is the most important thing when it comes to fruitfully iterating on the above adaptations.
Decide
Technical validation is half the battle, as with any migration. Once you've proven OSMs can match or surpass the functionality of your current closed source offering, you need to package these results and communicate the "why" to stakeholders.
Outline the effort needed to migrate to OSMs, what the risks are, and what the return on investment (ROI) is.
Some high level guidance from our experience:
Effort will define the actual workload needed to transition to OSMs. There are occasionally compatibility concerns for harnesses and tooling, but the gap here gets smaller every day. For instance togetherlink, a tool we provide makes it a simple install to start utilizing OSMs within any harness. Document any integrations or changes that would need to be made to fully utilize an OSM at scale.
Risks reflect traditional risks associated with adopting a new technology: compliance, scale, continued migration, familiarity with tooling, impacting downstream services. Document these and address them for your company's specific needs. A majority of these are addressed by managed providers if you choose to use one.
If you reach this stage with proper evals in place, this part can be greatly simplified, though you can still treat it as a loop that feeds back into evaluation.
ROI can be calculated as a quantifiable value from your evaluation stage. How many tokens can you generate per dollar? How does that compare to closed source? We see in some cases up to 70% cost reduction when customers transition to open source. You can do this for quality as well: how does quality compare to closed source? This will help define your ROI to stakeholders.
Ideally with risks, effort and ROI defined, the decision should be easy to make from there. Adoption at this point is more about education than technical boundaries.
Production
At the point of approval, the migration begins. As mentioned, traditionally moving to production following a migration is a long, drawn-out process. However, with transitioning from closed to OSM, we find this is actually one of the lightest steps.
We can learn from traditional migration practices to take inventory of your migration's impact and create a roadmap. We can base most of this on the effort and risks sections from earlier. Will we impact downstream services? How do we get a model approved via security and compliance teams? Are there any changes needed to tooling or services built on top of previous models? This shift doesn't need to be immediate either. Canary deployments have seen great success with our customers to validate against production use cases, starting with 10% of traffic to open source.
A roadmap consists of all the steps needed for your OSM adoption. This should include any security/compliance, technology changes or downstream service changes that need to be made. Don't be intimidated here, the technical implementation can be as simple as switching out an endpoint!
We understand that this is a very simplistic overview, but at its core we've seen this transition dozens of times with our largest customers and feel strongly that it's far less cumbersome than a traditional technical migration.
If you're going through a similar migration we encourage you to follow future blogs, or reach out to sales@together.ai for any questions. And we'd love any feedback on what may be missing here. Happy building!